How we measure what people will choose
AI now produces a hundred versions of a pack, a headline or a logo in an afternoon. This piece describes how we find out which one people will choose: we show real shoppers whole versions, score every part, and run the scores for every group. It also covers where the method comes from, and what to do when different groups want different things.
The exponent for electric shock. Brightness is 0.33. Each sense grows as a power of the stimulus, and the exponent is the slope of a straight line on log paper.
A loss hurts about twice as much as a gain of the same size feels good. The value curve bends at the point where you stand.
Types of reader found inside one crowd of 312 people, each reacting to a different part of the same sign. Moskowitz found the same kind of split in spaghetti sauce.
The short version
- A study does two things. It takes the work apart and measures each part with real people. Then it puts the parts back together in the combination that scores highest.
- The method comes from three researchers. Stevens showed that judgments follow a rule you can plot. Tversky showed that the rule bends, and that judgments add up from parts. Moskowitz showed that one crowd hides several groups. We use all three.
- Averages hide the split. A headline that scores +25 with one type of reader and −2 with another averages out to +11. The +25 and the −2 tell you what to do. The +11 does not.
- Machines make the versions. People choose. AI produces a thousand versions of anything. Only people can tell you which one other people will choose, so we ask them, in the market the work has to win, and report within a day.
Why choosing got harder
You've been in this meeting. Fifty packs on the table, or a hundred headlines in a document, or a logo in every style that exists, because the software that made them doesn't get tired. It took an afternoon. Five years ago it took a quarter and a budget.
Then someone asks which one. Everyone has an opinion. Nobody has a fact. The people who will actually choose, at the shelf, at the booth, on their phone, aren't in the room, so the team chooses for them. That feels like judgment. Mostly it's taste, which is one person's preference, and the shoppers have their own.
Making a version now costs almost nothing. Launching the wrong one still costs what it always did. Every month there are more versions to choose between and the same number of right answers, and that is the gap we started MindSurf to close. The method is decades old. The speed is new.
Taking apart and putting together
Making something new means combining: a new idea is two old ideas that hadn't met. Checking whether it works means separating: break the thing into parts, test each one, keep what holds. Designers are trained to do the first and analysts the second, and they usually sit in different rooms.
A study has to do both, because you can't improve a pack until you know which of its parts is doing the work. A cook who can't taste the salt apart from the acid can't fix the dish. A designer who can't tell what the photo is doing apart from what the headline is doing can't fix the pack, so they redesign the whole thing and lose the photo that was working.

Take it apart. Measure the parts. Put them back together better.
Machines are bad at this. A machine will give you a thousand combinations. It can't tell you which one a shopper will pick up, because it has never been a shopper. Shoppers can tell you, if you ask them properly.
Stevens draws a straight line
In 1957 Stanley Smith Stevens, who ran the Psycho-Acoustic Laboratory at Harvard, published a short paper that people still argue about. He had spent years asking volunteers to put a number on a feeling. How loud is this tone? Twice as loud as that one? Half? Brightness, heaviness, the sting of a small electric shock, all of it rated by ordinary people in a quiet room. Then he plotted the ratings against the physical stimulus on paper where both axes ran in powers of ten.
The points fell on straight lines.
A straight line on log paper means a power law: sensation grows as the stimulus raised to a fixed exponent, and the exponent is the slope. Each sense has its own. Brightness is about 0.33, so a light has to get eight times stronger to look twice as bright. Length is 1: a stick twice as long looks twice as long. Electric shock is about 3.5, so a small turn of the dial feels like a big one.
Two things came out of that picture. Human judgment, which everyone agreed was soft, obeyed a rule you could draw with a ruler. And the rule was different for each sense, so one line could be laid next to another and compared. A decade earlier Stevens had sorted every kind of number into four scales, nominal, ordinal, interval and ratio, and asked what arithmetic each one allows. That question decides what we may do with a score. When we say a photo is worth +7, that's a distance on a scale, not a rank, so it can be added to other distances.
Tversky draws a bend
Amos Tversky drew a different picture, with a kink in it. In 1979, with Daniel Kahneman, he plotted how people value gains and losses. The curve runs through the point where you're standing now. To the right, for gains, it rises and flattens: the second thousand dollars is worth less to you than the first. To the left, for losses, it drops and keeps dropping, about twice as steep.
That kink explains a lot. It's why people turn down fair bets, hold losing stocks too long, and rate the same beef higher as "75% lean" than as "25% fat". A fact framed as a loss moves people about twice as hard as the same fact framed as a gain. Tversky and Kahneman showed it in 1981 with a question about an epidemic, and it has held up in every replication since.
Tversky spent his career on the gap between what people do and what a tidy model says they should do, and he was precise about where the model still worked. With Krantz, Luce and Suppes he wrote down the conditions under which a judgment can be split into parts that add. That's the arithmetic under everything we do. A shopper's response to a whole pack can be read as the sum of their responses to its parts, so the parts can be measured one at a time, even though nobody ever sees them one at a time.
In 1977 he showed that even similarity is lopsided. People say North Korea is like China more readily than they say China is like North Korea, because similarity isn't a distance on a map. It's a comparison of features, and it depends on which thing you hold still. Every time we put two groups side by side, women and men, Greece and Saudi Arabia, we use that result. What looks close from one side can look far from the other.
Moskowitz finds the split
Howard Moskowitz did his doctorate under Stevens, then took the method out of the lab and into a kitchen. In the 1980s Campbell's asked him to find the best spaghetti sauce for Prego. He made dozens of versions, had people taste them, and then didn't do what he had been hired to do. He didn't look for the winner. He looked at the spread.
The scores didn't gather around one point. They split three ways. One group wanted the sauce plain, one wanted it spicy, and one wanted it with big pieces of vegetable, and no sauce like that was on the shelf. The average sauce, the one everyone had been optimising for years, was nobody's favourite. No single sauce scored best with everyone. Three different sauces did, one per group, and the chunky one became a very large business.
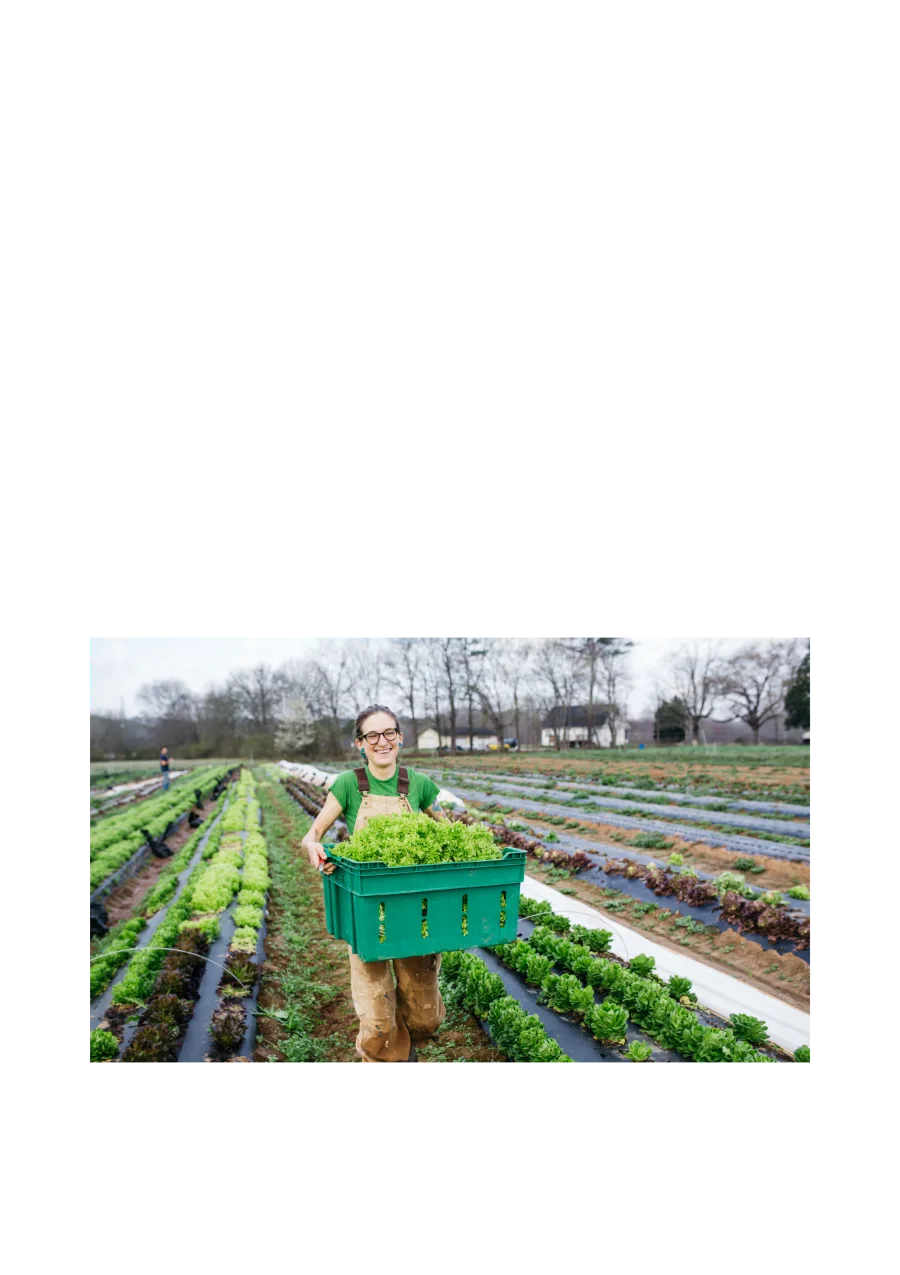
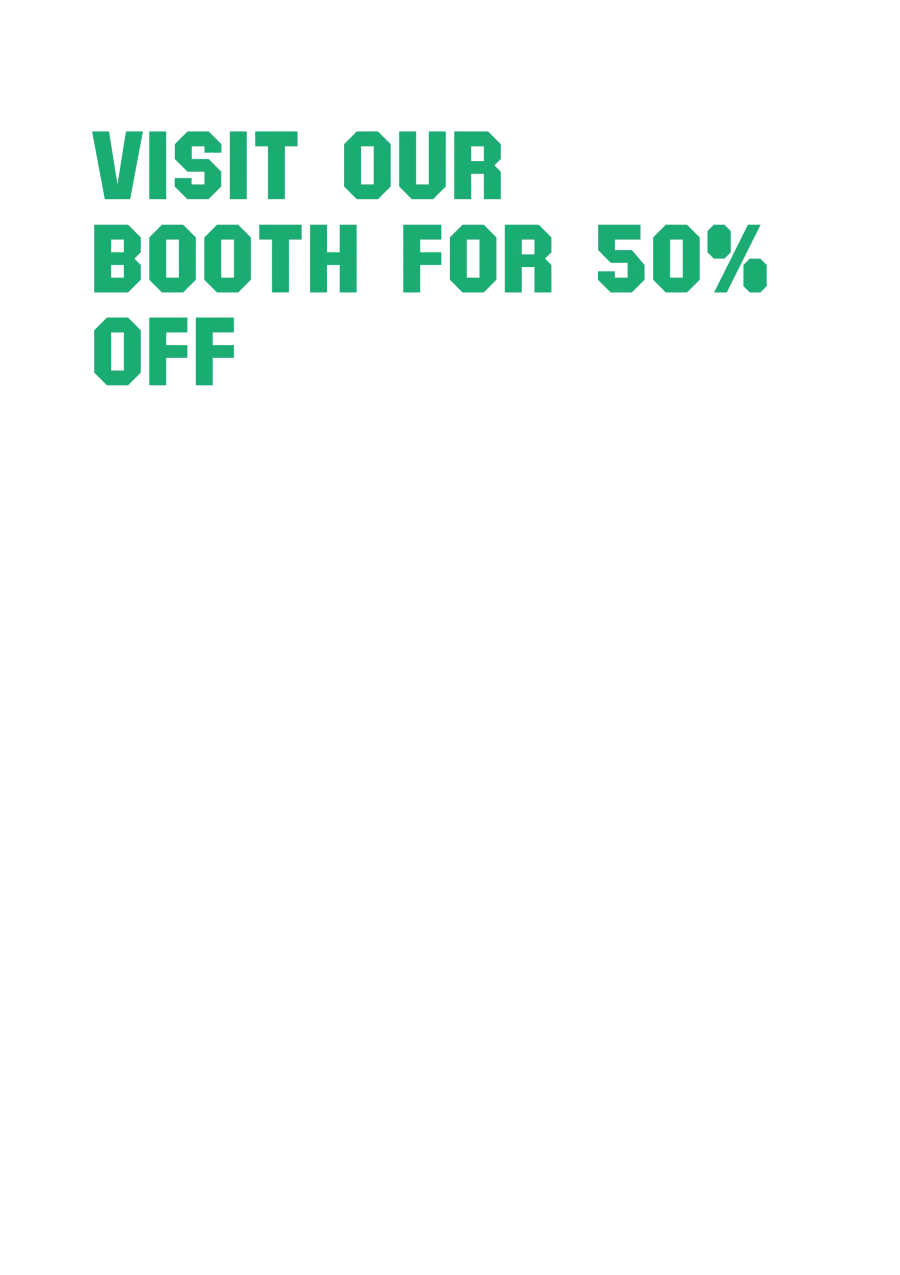
That pattern, one crowd breaking into a few groups, is the one we see most often. In a study of a sign for an online farmers market in Atlanta, the average said what averages say: lead with an offer. The spread said something more useful. There were three types of reader in front of that sign. 121 read the headline. 105 read the small print under it. 86 read the strip along the bottom, and each group was close to blind to what the other two were reading. The same headline scored +25 with the headline readers and −2 with the small-print readers, with the same words on the same sign.
Moskowitz called these groups mind-sets: people who look at the same thing and see different parts of it. A mind-set isn't an age or a gender. It shows up at every age and in both genders, and you'll never find it by asking people how old they are.
How the numbers work
Each of the three pictures gives you a different kind of number. The line gives you direction: more of this gets more of that, at a rate you can read. The curve gives you asymmetry: the same distance isn't the same distance both ways. The cloud gives you separation: the crowd was never one thing.
A MindSurf study gives you all three from one set of ratings.
Each person sees whole versions of the work, one after another, for a few seconds each: a sign with this headline, that photo and that line at the bottom, then a sign with different ones. Nobody is asked what they think of a headline. They're asked whether they'd stop, buy or click, and they answer with the whole thing in front of them, the way they will in the real world, where no one is ever shown a headline on its own.
Then we run the arithmetic the other way. Because the parts were combined by design, we can work out what each one added to or took from the chance of a yes, and every part gets a number. A blank sign scores 50. The cotton background adds one, the discount headline eleven, the line of small print six, the farm photo seven and the strip along the bottom three, and 78 in 100 would stop.
Then the same arithmetic runs for every group you can name: women, men, each age, each market, each mind-set. Now every number has a direction, a size and a group it belongs to. It's a grid of scores, one for each part and each group, some positive and some negative. In our experience it's the first time most teams have seen their own work as parts.
Where averages fail
The grid is most useful where the groups disagree.
The same protein cookie, in the same pack, scored 65 in Greece and 90 in Saudi Arabia. On the Atlanta sign, "Organic groceries, fair prices" added seven points with people aged 35 to 54 and took ten away with people aged 55 to 64. "Guess the price of our box to win" moved men 13 points and women 2. "Seasonal eating made easy", on the strip along the bottom, was worth +11 to one type of reader and −10 to another.
Averaged across everyone, those three parts score +2, +5 and 0, and the sign looks like it barely matters. Split by group, it matters a lot, in opposite directions, to people who will walk past it minutes apart. The average is correct and nearly useless here, and it is usually the only number a team sees.
A contradiction like that is useful. It tells the designer which part to change for which group, and by how much.
What to do with a split crowd
Once the scores show that the crowd is split, the team has to decide what to make. There are three answers.
Pick one group. Make it for the group that matters most and accept the cost with the rest. A pet-sitting company's design team wanted its minimalist icons. The pet owners who would actually hire a sitter trusted the illustrated logos, by about 20 points on average. The company chose the pet owners. It's the simplest answer, and often the right one.
Give each group its part on one object. Build one thing that carries something for everyone. The Atlanta sign built for everyone scored 86 with the headline readers, 80 with the small-print readers and 62 with the bottom-strip readers, because it carried a strong headline, a strong line of small print, and a bottom strip the third group could live with. Three tailored signs would have added one, six and five points. Not worth three signs.
Put the winning parts together. Take the part that wins in one place and the part that wins in another and put them on one object. The cookie pack that went to print was the agency's winning design with its flavour name reset in dark type, borrowed from a design that lost. Nobody had proposed it. The numbers said it would work, and it added ten points in every market. For scale, the gap between the best and worst of the three designs as drawn was three points.
None of the three comes from the average. All three come from the split, and the split only shows up because each part was measured on its own.
What we're building
MindSurf is a research company. We test creative work with real people in the market it has to win, and we come back with the numbers in a day. Each study is designed around the work, so the parts the team can actually change are the parts that get measured. Nobody pays to learn something they can't act on.
We're building that into a service that tests every pack, headline, logo, price and name with the people it's for before it ships, and returns the numbers before the next version is made. It replaces the quarterly focus group with a measurement at every decision.
Making gets cheaper every year and choosing does not, so the value of knowing what people will choose keeps rising. We intend to be the company that measures it. The method is Stevens' numbers, Tversky's curve and Moskowitz's clusters, run at the speed of the machines that now make the work.
Human intelligence at the speed of AI.
Send us one decision.
A pack, a logo, a sign, a name, a price. We'll design the study around it, put it in front of the right people, and show you where they split and what that lets you combine.
References
- Stevens, S. S. (1946). On the theory of scales of measurement. Science, 103(2684), 677–680.
- Stevens, S. S. (1957). On the psychophysical law. Psychological Review, 64(3), 153–181.
- Krantz, D. H., Luce, R. D., Suppes, P., & Tversky, A. (1971). Foundations of Measurement, Vol. I: Additive and Polynomial Representations. Academic Press.
- Tversky, A. (1977). Features of similarity. Psychological Review, 84(4), 327–352.
- Kahneman, D., & Tversky, A. (1979). Prospect theory: An analysis of decision under risk. Econometrica, 47(2), 263–291.
- Tversky, A., & Kahneman, D. (1981). The framing of decisions and the psychology of choice. Science, 211(4481), 453–458.
- Levin, I. P., & Gaeth, G. J. (1988). How consumers are affected by the framing of attribute information before and after consuming the product. Journal of Consumer Research, 15(3), 374–378.
- Tversky, A., & Kahneman, D. (1992). Advances in prospect theory: Cumulative representation of uncertainty. Journal of Risk and Uncertainty, 5(4), 297–323.
- Moskowitz, H. R., & Gofman, A. (2007). Selling Blue Elephants: How to Make Great Products That People Want Before They Even Know They Want Them. Wharton School Publishing.
- Gladwell, M. (2004). Choice, happiness and spaghetti sauce. TED.
- MindSurf (2026). Testing a farmers market sign in Atlanta. A Fresh Harvest sign study, 312 people.